Backup Corruption and Bit Rot: How to Detect and Prevent
Bit rot is silent data corruption: stored data changes without any error message, so you only find out when something checks it. It does happen, but nobody can give you a trustworthy rate for your own disks. The practical defense is checksums, regular scrubs, backup verification, versioned copies and restore tests, because only a test proves a backup works.
Updated · Mr.PlanB
What bit rot and silent corruption mean
People use "bit rot" for any case where data you stored comes back different from what you wrote, with no warning. The word suggests slow decay of the storage medium, and that does happen on hard disks, SSDs and tape. But the same symptom has other causes: a torn write when power fails, a write that lands on the wrong sector, a firmware bug, a flipped bit in memory before the data reaches the disk, or damage in transit across a network. Researchers call these silent data corruption.
The word silent matters. A disk that cannot read a sector reports an error, and software can react. Silent corruption means the disk returns data without complaint, and the data is wrong. Nothing in the system knows until a checksum, a comparison or a person notices.
What can and cannot be measured
Silent corruption can only be counted where something is checking. Ordinary systems without checksums never see it, which is why you rarely hear "I have never had corruption" from someone who also never verified anything.
The best known measurement is a study of NetApp storage systems by Bairavasundaram and colleagues, presented at the USENIX FAST conference in February 2008. It looked at about 1.53 million disk drives over 41 months and found more than 400,000 checksum mismatches. In the first 17 months in the field, about 0.66 percent of nearline (SATA) disks and about 0.06 percent of enterprise disks developed at least one mismatch, according to the paper. It also found that mismatches cluster in space and time on a disk, and that nearline disks showed them about ten times as often as enterprise disks.
Treat those numbers with care. They describe specific arrays and disk models from before 2008, and a checksum mismatch in the study covers several causes, not only decaying bits. They show that silent corruption is real and measurable. They do not give you a rate that applies to your own disks, your SSDs or today's drives, and this article does not offer one. If you need to know your own exposure, the only way is to run checksummed scrubs and read the results.
Where corruption enters, and what catches it
Corruption can enter at several places on the way from application to disk and then again while a backup sits in storage. Each place has a different control, and none of them covers all the others.
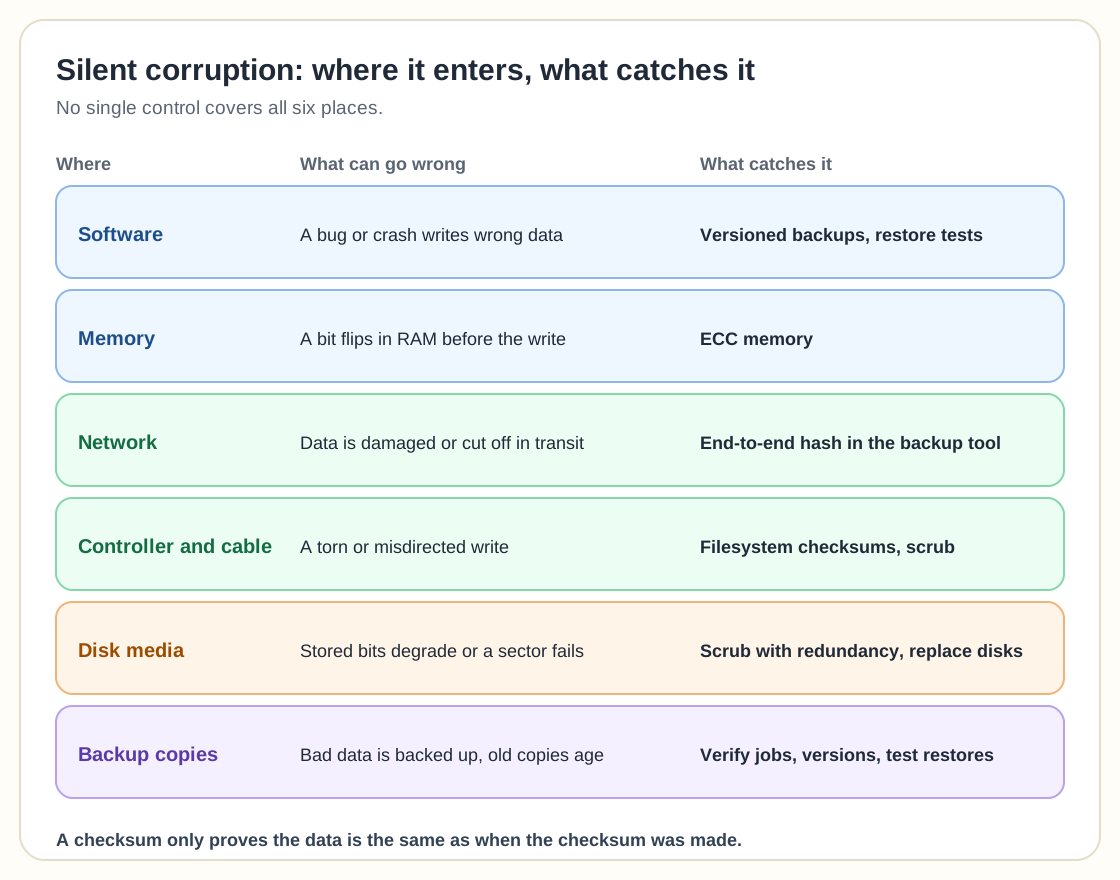
Two points in the diagram deserve a note. Memory errors happen before the data reaches the disk, so a filesystem that computes its checksum after the damage will faithfully protect the wrong data. ECC memory addresses that step: it can correct a single flipped bit and detect some larger errors. And a checksum only proves the data is unchanged since the checksum was made. It cannot tell you the data was right when it was first written.
How checksums, scrubs and verification protect data
Checksumming filesystems and scrubs
ZFS and Btrfs store a checksum for every block and check it on every read. A scrub goes further: it reads all the data on purpose, so damage in files you have not opened for years is found too. In ZFS, the OpenZFS documentation says a normal scrub "verifies each block's checksum" and, on mirror, raidz and draid pools, automatically repairs damage it finds. A pool with no redundancy can detect errors but has no second copy to repair from. The OpenZFS pages give no fixed schedule and provide weekly and monthly scrub timers for systemd systems. Our ZFS guide covers pool layouts and scrubbing in more detail.
Btrfs scrub is also a validation pass over all data and metadata that detects checksum errors. According to the Btrfs documentation, repair works by copying verified good data from another replica, so it needs a redundant profile such as RAID1. Files marked NOCOW are not covered by data checksums, so Btrfs cannot tell which copy is good for them.
Ceph scrubbing
Ceph runs two kinds of scrub. A light scrub compares object sizes and attributes and usually runs daily. A deep scrub reads the stored data and verifies checksums, usually weekly, and the default deep scrub interval is 7 days. If you run Ceph under Proxmox, see our Ceph overview.
End-to-end verification in the backup tool
Backup software should hash data when it reads it and check the hash after it arrives. That catches damage on the network and in the target storage. Backup repositories also need their own checks. Restic's check command verifies the repository structure by default, and with --read-data it reads every pack file to confirm it is unchanged, which downloads everything and can cost bandwidth. The --read-data-subset option checks a part of the repository per run so the full pass is spread over time. Proxmox Backup Server runs verify jobs on a schedule, and its documentation warns that a backup that was fine once can degrade later and recommends re-verifying all backups at least monthly.
Restore tests
Verification proves the stored bytes match their checksums. A restore test proves you can get a working system or file back. Pick a random backup, restore it to a clean place, open the files or start the machine, and write down how long it took. Our backup testing guide has a schedule and a checklist. The Proxmox backup strategy for 2026 article shows how this fits a real plan.
Why a backup of corrupted data is useless without versions
A backup copies what the source holds. If the source has been damaged and the backup software runs a sync or mirror, the good older copy gets replaced by the damaged one on the next run. Deduplicating repositories add a second risk: when one chunk is shared by many snapshots, one damaged chunk can damage all of them, which is why repository checks matter.
Versions solve the first problem. With several restore points, kept for weeks or months, you can go back to a copy from before the damage. Retention is part of the protection, so a one-copy mirror is not a backup of the same quality. Read snapshots versus backups and why snapshots alone are not enough for the difference, and how to set a retention policy for Windows Server.
A practical routine
Use a checksumming filesystem with redundancy for the primary data and for backup storage where you can, and schedule regular scrubs.
Use ECC memory on servers and storage systems that hold important data.
Keep at least three copies with the 3-2-1-1-0 rule, where the last 0 means zero errors after verification.
Keep several versions and an offsite copy that a damaged or compromised source cannot overwrite.
Run repository verification on a schedule and full restore tests at least a few times a year.
Read the scrub and verify reports. A job that runs but nobody reads protects nothing.
FAQ
Is bit rot common on modern hard drives?
Nobody can give a reliable rate for your drives. Large studies show silent corruption happens and clusters on some disks, but the best known data is from 2008 enterprise arrays. Run scrubs and read the results to learn your own exposure.
How do I detect backup corruption?
Use a tool or filesystem that stores checksums, run scrubs or repository verification on a schedule, and test restores. Without checksums, corruption stays invisible until you try to open the file.
Are ZFS and Btrfs worth it for backup storage?
They detect silent corruption on every read and in scrubs, and they repair it when a redundant copy exists. Without redundancy they only tell you something is wrong. They do not replace a second copy of the backup.
Does ECC memory protect against bit rot?
ECC protects data while it sits in memory, before it is written. It does not protect data on a disk, so it complements scrubs and checksums and does not replace them.
Related guides
More from the backup hub on the same topics.
Need help with backup and recovery?
Use the form below to get in touch about backup strategy, recovery planning, and data protection projects.